


In a café
Without Clarity
Chatter keeps turn detection busy, so your agent waits or interrupts.
With Clarity
Your agent answers when the caller stops talking.
Clarity removes background noise in real time and, with a short voice sample, every voice but the caller’s.
Press play, then switch Clarity on.
Each sample: a caller, a quieter second talker and the noise of the place.
Without Clarity
Chatter keeps turn detection busy, so your agent waits or interrupts.
With Clarity
Your agent answers when the caller stops talking.
Without Clarity
Voices from the crowd end up in the transcript.
With Clarity
The transcript holds what the caller said.
Without Clarity
A colleague’s “yes” counts as the caller’s answer.
With Clarity
With a 2 to 8 second voice sample, your agent hears only the caller.
On both public benchmarks, Clarity 1 gives your agent the cleanest audio of any streaming model in the test.
Libri2Mix · DNSMOS, higher is better
| Metric | Clarity 1240 ms | StarTSE[1]560 ms |
|---|---|---|
| Speech quality SIG | 3.56 (best) | 3.54 |
| Background quality BAK | 4.03 (best) | 3.75 |
| Overall quality OVRL | 3.27 (best) | 3.12 |
DNS 2020 Challenge · DNSMOS, higher is better
| Metric | Clarity 1240 ms | UnprocessedOriginal audio | AI Acoustics15 ms | DeepFilterNet310 ms | GTCRN16 ms |
|---|---|---|---|---|---|
| Speech quality SIG | 3.62 (best) | 3.39 | 3.46 | 3.51 | 3.34 |
| Background quality BAK | 4.11 (best) | 2.62 | 3.60 | 4.11 (best) | 3.98 |
| Overall quality OVRL | 3.37 (best) | 2.48 | 2.98 | 3.25 | 3.05 |
DeepFilterNet3 ties on background quality without reverb; offline models, which need the whole recording first, score up to 0.08 higher on speaker extraction.
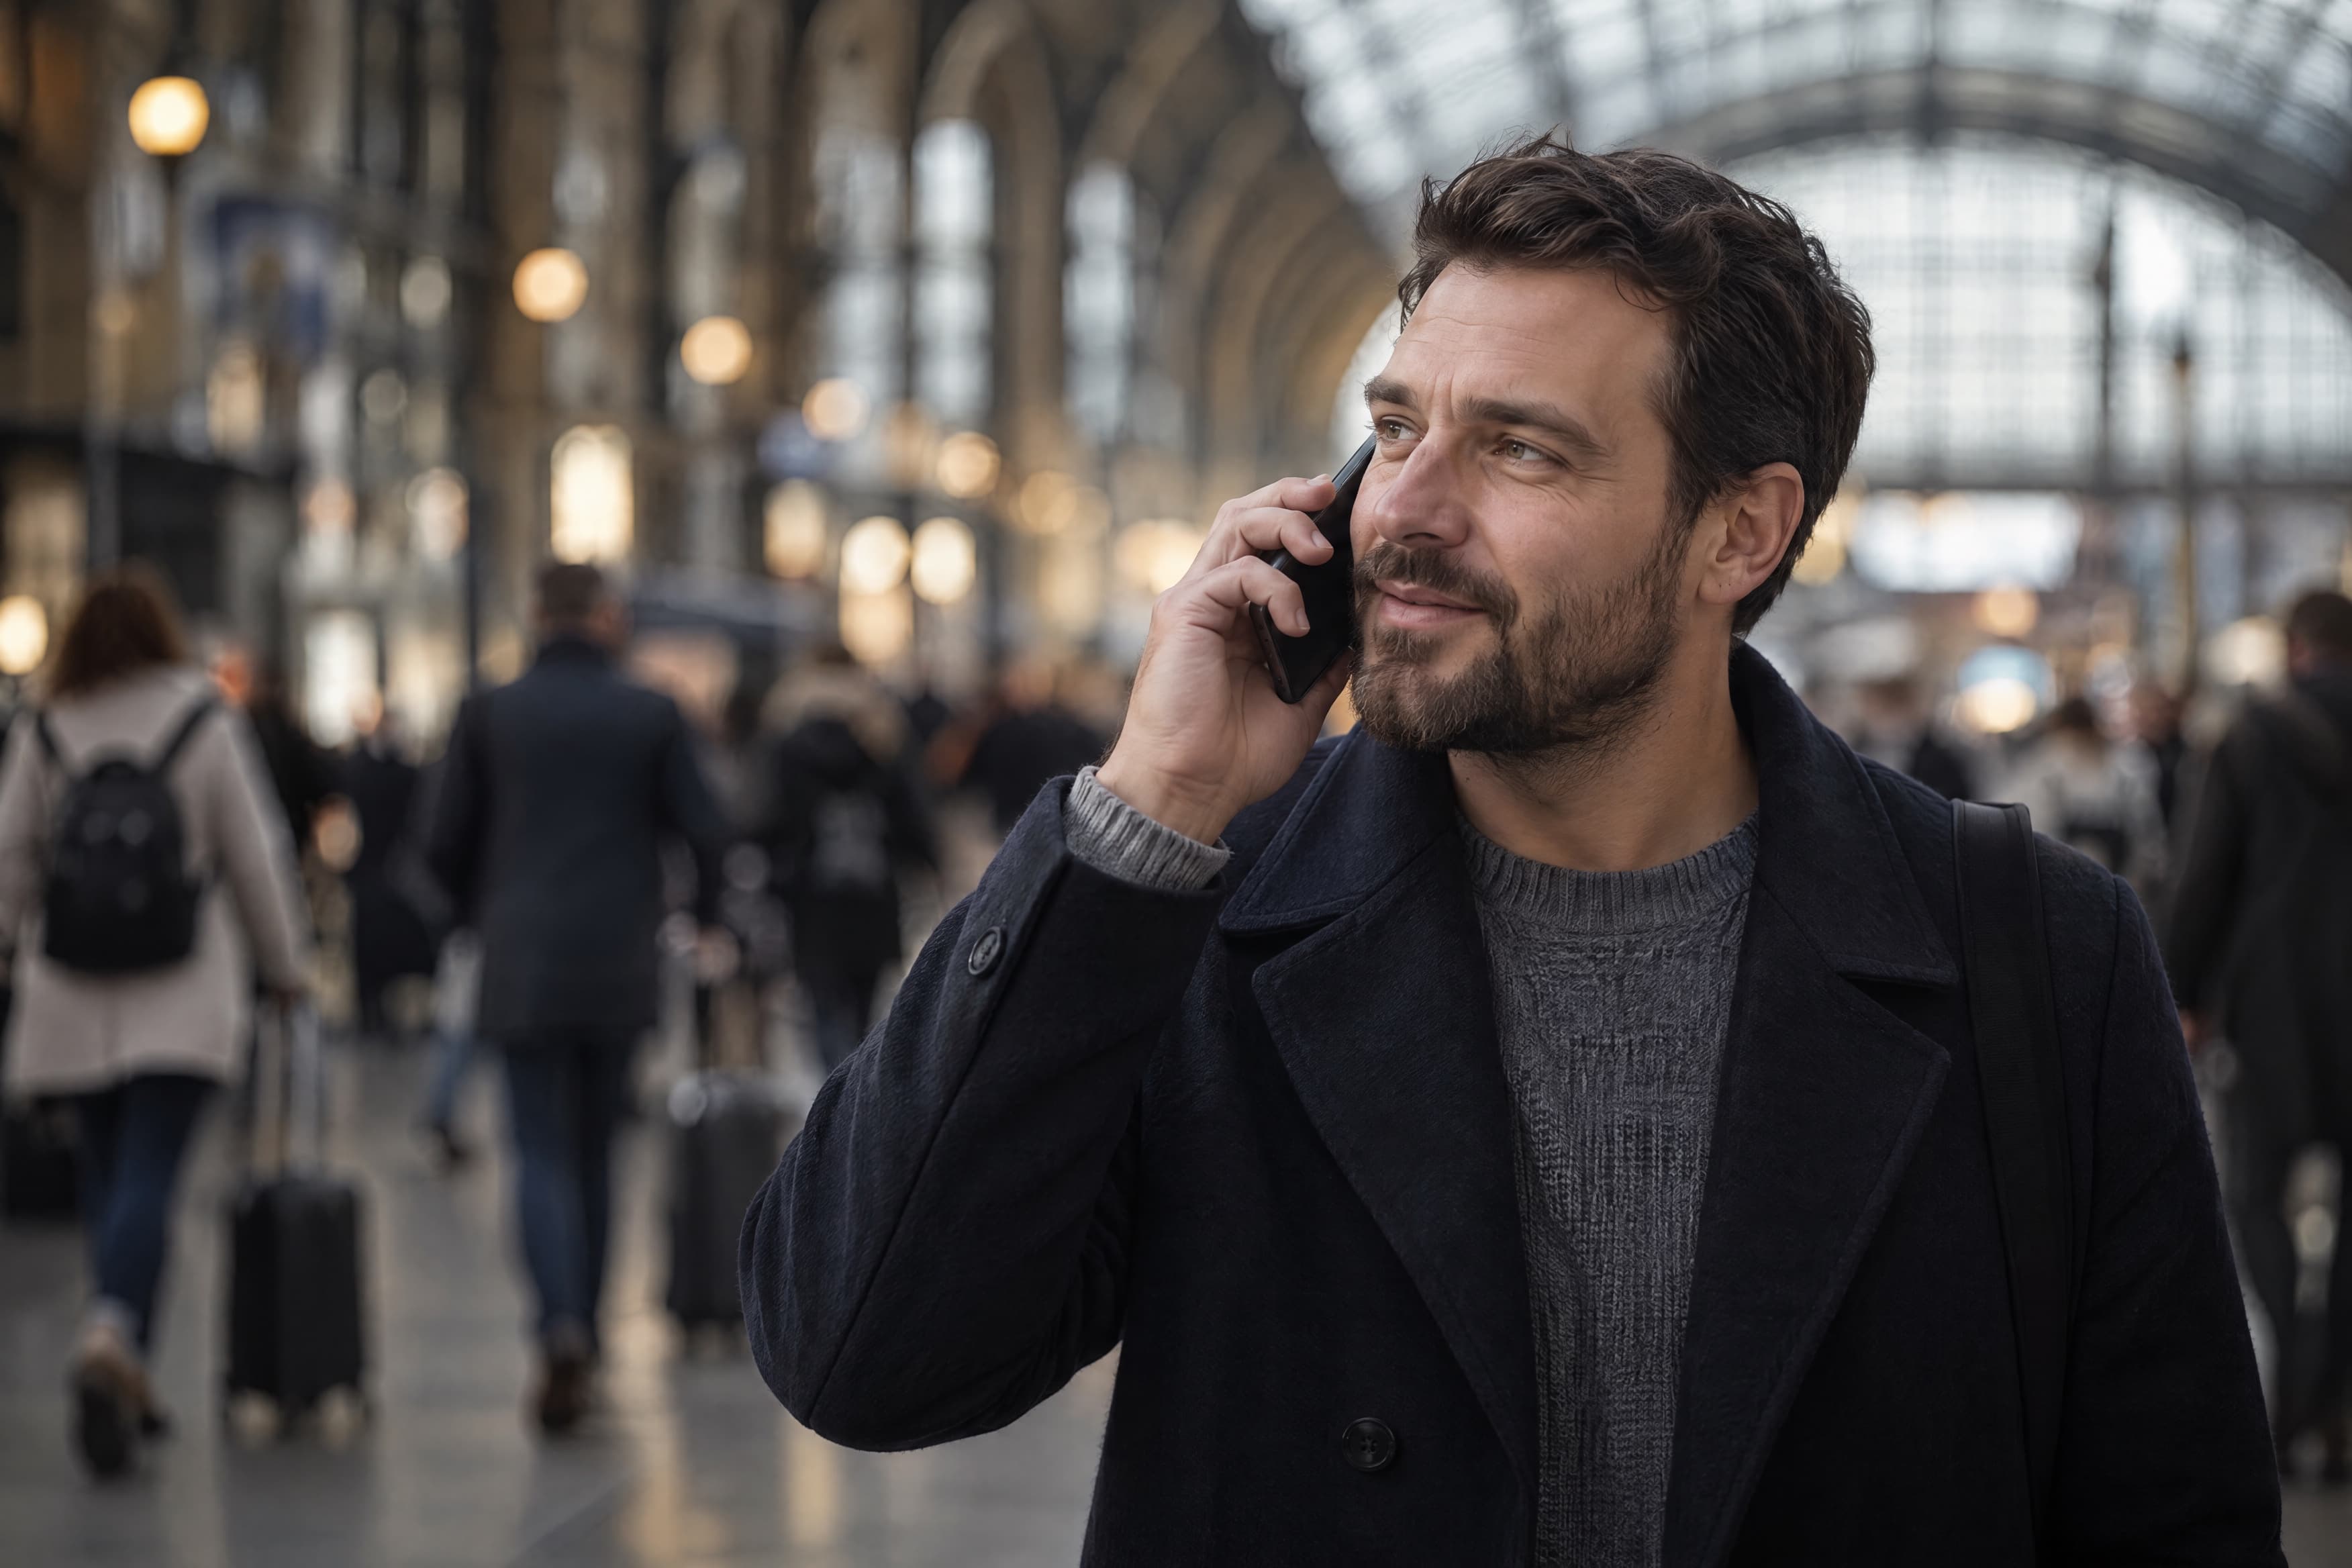
Your agent hears only the caller, even in a station hall.
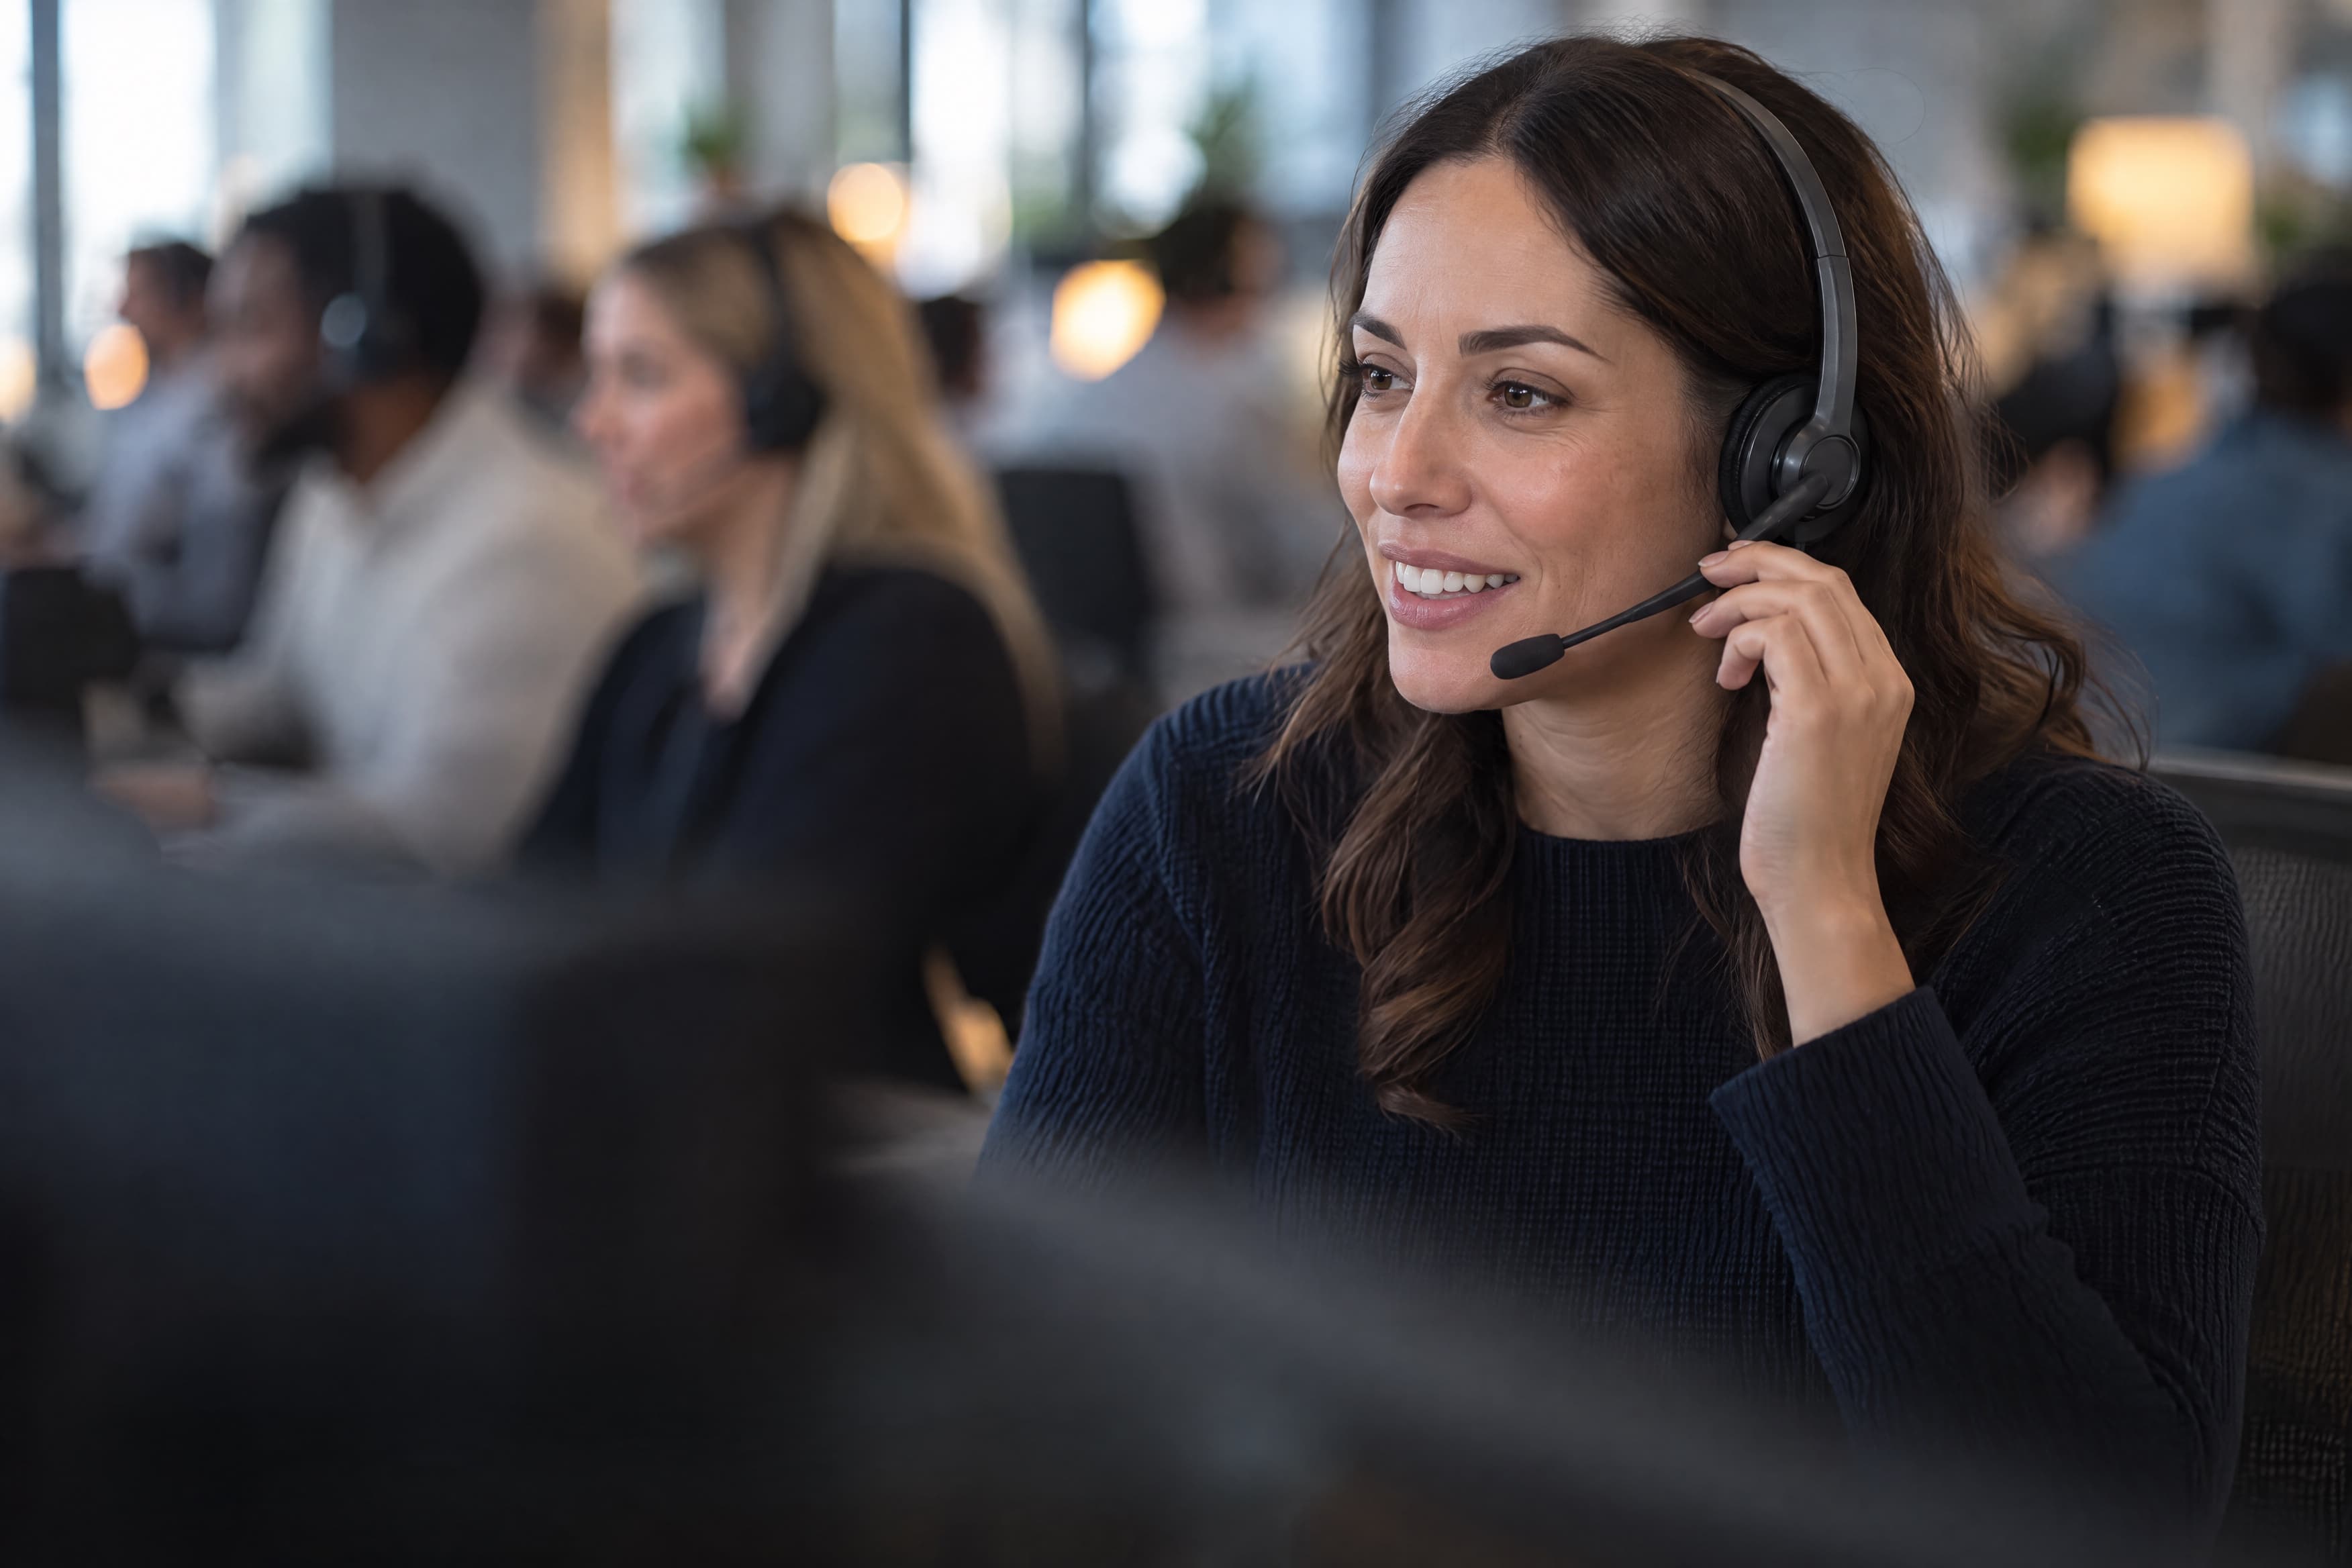
Customers hear your agent, without the noise, echo and colleagues around her.
Clarity sits on your agent’s audio input and streams, so everything after it works from the cleaned caller.
from livekit.agents import room_io
from kugelaudio import load_audio
from kugelaudio.livekit import enhancement

await session.start(
    room=ctx.room,
    agent=agent,
    room_options=room_io.RoomOptions(
        audio_input=room_io.AudioInputOptions(
            noise_cancellation=enhancement(),  # reads KUGELAUDIO_API_KEY
            # keep one voice: enhancement(speaker=load_audio("caller.wav"))
        ),
    ),
)clarity-1POST /v1/audio/enhanceWS /v1/audio/enhance/stream€0.0015per audio minute, excl. VAT
Billed from your credits per second of input audio, rounded up, one second minimum. Failed requests are not billed.
Get startedSelf-hosting and on-premise deployment, on Enterprise plans.
KugelAudio’s line of speech enhancement models. Clarity 1 (clarity-1) removes background noise and, with a speaker sample, keeps only that voice, on recordings and live audio.
About 50 ms if your pipeline already reads audio in 240 ms chunks. With smaller frames, a sound can come out up to 290 ms after it went in.
From a 2 to 8 second sample of that person, ideally alone and with little noise. Without a sample, Clarity removes noise and keeps the speech.
WAV at 8 to 48 kHz, up to 300 seconds per recording, or live 16 bit PCM over a WebSocket. The output is mono 16 bit PCM at 24 kHz.
Yes. Self-hosting and on-premise deployment are available on Enterprise plans.